You signed in with another tab or window. Reload to refresh your session.You signed out in another tab or window. Reload to refresh your session.You switched accounts on another tab or window. Reload to refresh your session.Dismiss alert
Introduction: this LLM model is one the varients of GPT models but relatively smaller one (NanoGPT), a single book is used to train this model.
tools used are Python, PyTorch, and Matplotlib
The data used to train is a single book as mentioned, The wizerd of Oz, dictionary: 9333 words length: 38261 words
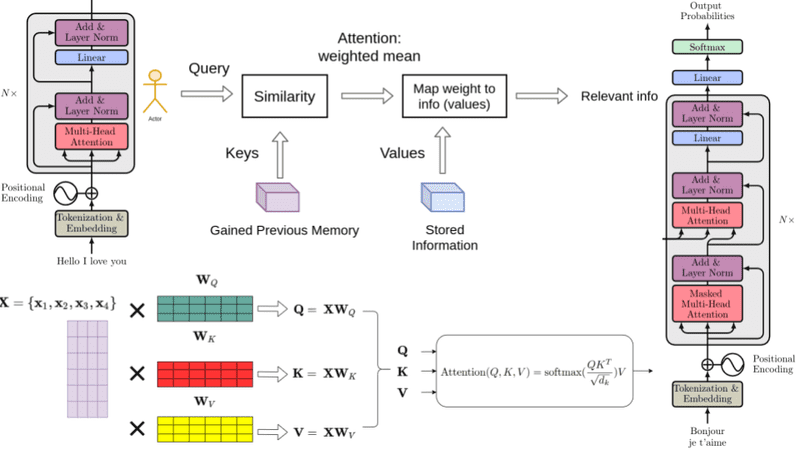
for the arch. part, transformers is used, to get help of its multihead attention, the hyper-parameters: batch_size = 64 block_size = 256 max_iters = 5000 eval_interval = 500 learning_rate = 3e-4 eval_iters = 200 n_embd = 384 n_head = 6 n_layer = 6 dropout = 0.2
Conclusion: In this project, we developed a Language Model (LM) based on the NanoGPT architecture, trained using text from "The Wizard of Oz." Leveraging Python, PyTorch, and the Transformers library, we optimized hyperparameters for effective training. The model demonstrated the ability to generate coherent text, showcasing the effectiveness of transformer-based LMs in natural language processing tasks, even with limited data and computational resources.
References:
- "The Wizard of Oz." Wikipedia, Wikimedia Foundation, 25 Mar. 2024. - Vaswani, Ashish, et al. "Attention Is All You Need." Advances in Neural Information Processing Systems, vol. 30, 2017. - Wolf, Thomas, et al. "Hugging Face's Transformers: State-of-the-art Natural Language Processing." ArXiv:2003.05565 [Cs], 2020. - PyTorch Documentation. - Hugging Face Transformers Documentation.